

Cutshort Lightning
https://cutshort.ioAbout
Company social profiles


Jobs at Cutshort Lightning
 Javascript
 NodeJS (Node.js)
Job Responsibilities:
- Design an API, not only implement one.
- Reason about indexes, query plans, transactions, migrations on live tables.
- Handle vendor and third-party integrations, done well: authentication, retries, idempotency, webhooks, rate limits, sandbox-to-production rollout, and reconciliation when the other side fails mid-flow.
- Work directly with a vendor's technical team to get an integration over the line.
- Manage Queues, background jobs and scheduled work, including what happens when a job runs twice.
- Perform React with TypeScript.
- Execute Component design, state management, forms that hold up under real user behaviour.
- Build a clean screen without a pixel-perfect design handed to you using enough CSS and layout sense.
- Ensure Performance and correctness on the browser side: loading states, error states, the ugly edge cases.
- Write Tests you actually write.
- Maintain Git discipline, CI/CD, and enough DevOps grounding to be self-sufficient: containers, environment configuration, pipelines, deployments and rollbacks.
- Understand AWS fundamentals: how your service runs, scales and fails.
- Instrument what you build logs, metrics, alerts so problems surface on a dashboard rather than in a customer complaint.
- Read monitoring output and act on it: triaging an alert, finding the root cause, and closing the loop with a fix or a tuned threshold rather than muting it.
- Keep an eye on infrastructure cost.
- Know roughly what your service costs to run, spotting the query, log stream or API call pattern that is quietly expensive, and factoring that into design decisions.
- Understand the problem first-hand.
- Spend time with the product owner or the ops team that has the problem, and see how the work happens today rather than working from a requirements document alone.
- Design, build and ship end to end.
- Take it to production and keep it healthy.
- Deploy it, monitor it, and act on what the monitoring tells you.
- Watch for Errors, latency, failed jobs and data quality and ideally spot the issue before someone reports it.
- Be mindful of what it costs to run.
- Think about instance sizing, storage, query patterns, log volume and the cost of third-party API calls before you ship, and raise it early when something is likely to get expensive.
- Integrate cleanly with vendors and partners.
- Work well with vendor teams, reading their documentation carefully and handling their failure modes gracefully.
- Be accountable for what you commit to.
- Give estimates you believe in, flag slippage early, and keep the status visible.
- Leave it documented.
- Build securely by default.
Skills Required:
JavaScript , TypeScript , Node.js , API Design , Relational Data Modelling , SQL , Indexing , Query Optimization , Transactions , Database Migrations , Vendor Integration , Authentication , Retries , Idempotency , Webhooks , Rate Limiting , Queues , Background Jobs , Scheduled Work , React , Component Design , State Management , Forms , CSS , Layout Design , Performance Optimization , Error Handling , Testing , Git , CI/CD , DevOps , Containers , Environment Configuration , Pipelines , Deployments , Rollbacks , AWS , Monitoring , Logging , Metrics , Alerting , Cost Awareness , Problem Solving , Communication , Accountability , Documentation , Security , Risk Management , Architecture Design , Trade-off Analysis
Candidate Attributes:
- Passion and hunger to make a dent in the MSME ecosystem.
- Comfortable with ambiguity and will go and resolve it, often by asking the ops or product team directly.
- Share status without being prompted, including when the news is not good.
- Care whether the change worked for the business, not only whether the story was closed.
- Own outcomes, not tickets.
- Sets the plan; trusted with the hardest and riskiest work.
- Owns architecture and the trade-offs behind it.
- Partners with function heads; helps decide what not to build.
 PythonNodeJS (Node.js)
 Amazon Web Services (AWS)
Role overview
The client is building a multimodal AI platform that processes multi-hour video, audio and text to generate structured insights, narratives and highlight workflows for broadcasters and media organisations.
We are seeking a Backend / Platform Engineer to design and build high-throughput media pipelines, robust APIs, and model-serving infrastructure that connect our AI engine (video perception + multimodal reasoning) to real products and customer environments.
This is not a CRUD‑only backend role.
You will work on:
- long‑running jobs
- distributed processing
- GPU inference orchestration
- storage for embeddings and metadata
- integration with AI models
- reliability and observability at scale
Key responsibilities
Media ingestion & processing pipelines
- Design and implement ingestion pipelines for multi‑hour video and audio content.
- Build microservices for frame extraction, audio processing, transcription integration and metadata generation.
- Handle long‑running, asynchronous jobs using queues, workers and robust retry strategies.
- Integrate with FFmpeg or similar tools for transcoding, segmenting and preparing media for AI models.
API & platform architecture
- Design and implement REST/gRPC APIs that expose AI model outputs (perception, multimodal alignment, narratives) to frontend and external systems.
- Define clear contracts for internal services and external integrations.
- Implement authentication, authorisation and rate‑limiting for platform endpoints.
- Ensure backward‑compatible API evolution as the product matures.
Model‑serving & AI integration
- Integrate with AI inference services (video models, multimodal models, LLM/VLM) running on GPUs or specialised infrastructure.
- Design request/response flows that handle large payloads, streaming outputs and structured results.
- Optimise throughput and latency for inference pipelines, including batching, caching and concurrency control.
- Collaborate closely with AI engineers to productionise models and debug end‑to‑end behaviour.
Storage, data models & performance
- Design data models to store embeddings, timelines, metadata, scene/shot boundaries, and narrative units.
- Work with appropriate storage technologies (SQL/NoSQL, object storage, search indices) based on access patterns.
- Implement indexing and query strategies for fast retrieval of segments, highlights and multimodal insights.
- Optimise performance for large datasets and high‑volume workloads.
Reliability, observability & operations
- Implement logging, metrics and tracing across services for debugging and monitoring.
- Set up health checks, circuit breakers and graceful degradation for critical services.
- Work with CI/CD pipelines to ensure safe, repeatable deployments.
- Collaborate on Kubernetes‑based deployments (or equivalent orchestration) for scaling services.
Requirements (must‑have)
Experience:
- 4–8 years in backend or platform engineering.
- At least 3 years working on distributed systems, high‑throughput services or complex pipelines (not just simple CRUD apps).
Languages & frameworks:
- Strong proficiency in Python or Node.js (one primary, both are a plus).
- Experience with at least one modern backend framework (FastAPI, Flask, Express, NestJS, etc.).
Distributed systems & pipelines:
- Hands‑on experience with queues and workers (e.g. Celery, RabbitMQ, Kafka, SQS, etc.).
- Experience building asynchronous, long‑running job pipelines.
- Understanding of idempotency, retries, backoff, and failure handling.
APIs & integration:
- Strong experience designing and implementing REST APIs (gRPC is a plus).
- Experience integrating with external services and handling network‑level failures.
Cloud & infrastructure:
- Experience deploying services on AWS, GCP or Azure (EC2/Compute Engine, S3/GCS, IAM, networking basics).
- Experience with Docker; exposure to Kubernetes is a strong plus.
Data & storage:
- Experience with SQL and at least one NoSQL store.
- Ability to design schemas and data models for performance and maintainability.
Engineering quality:
- Strong debugging skills across services and environments.
- Experience with unit/integration tests for backend systems.
- Clear, structured communication in English.
Nice‑to‑have
- Experience with media/video processing (FFmpeg, transcoding, segmenting).
- Experience with AI/ML model integration (serving models, handling inference requests).
- Experience with search/retrieval systems (e.g. Elasticsearch, vector databases).
- Experience with observability stacks (Prometheus, Grafana, OpenTelemetry).
- Experience working with remote teams across time zones.
What we are explicitly NOT looking for
To reduce noise and mismatches, we are not looking for:
- Pure CRUD‑only backend developers with no pipeline or distributed systems experience.
- Engineers who have only worked on small, single‑service apps without scale or complexity.
- Candidates who cannot explain trade‑offs in architecture, data modelling and reliability.
- Candidates who are uncomfortable with ownership of subsystems end‑to‑end.
Why join us
- Work on real, complex problems at the intersection of media, AI and distributed systems.
- Collaborate with senior AI engineers working on perception, multimodal fusion and narrative reasoning.
- Build the core platform that turns AI models into a usable product for broadcasters and media organisations.
- Operate with high ownership, clear expectations and direct access to the CTO.
 JavaPythonNodeJS (Node.js)
 React.js
 Angular (2+)
We are looking for a Full Stack Developer to build scalable software solutions and contribute across the entire software development lifecycle—from conception to deployment.
You will work closely with cross-functional teams and should be comfortable with both front-end and back-end technologies, modern frameworks, and third-party libraries. If you enjoy building visually appealing, functional applications and thrive in Agile environments, we’d love to connect.
Current Technologies Used
- Backend: FastAPI (active), PHP (legacy), Java (legacy)
- Frontend: Svelte, TypeScript, JavaScript
Experience with Python and PHP is a plus, but not mandatory.
Role Responsibilities
- Collaborate with development teams and product managers to ideate software solutions
- Design client-side and server-side architecture
- Build visually appealing front-end applications
- Develop and manage efficient databases and applications
- Write effective and scalable APIs
- Test software for responsiveness and performance
- Troubleshoot, debug, and upgrade systems
- Implement security and data-protection measures
- Build mobile-responsive features and applications
- Create and maintain technical documentation
Candidate Requirements:
Education
- B.Tech / BE in Computer Science, Statistics, or a relevant field
Experience
- 2–4 years as a Full Stack Developer or in a similar role
Location
- Bangalore (Hybrid)
Skill Set – Role Based
- Experience building web applications
- Familiarity with common technology stacks
- Knowledge of front-end languages and libraries:
- HTML, CSS, JavaScript, XML, jQuery
- Knowledge of back-end languages and frameworks:
- Java, Python, PHP
- Angular, React, Svelte, Node.js
- Familiarity with:
- Databases: PostgreSQL, MySQL, MongoDB
- Web servers: Apache
- UI/UX principles
Skill Set – Behavioural
- Excellent communication and teamwork skills
- Strong attention to detail
- Good organizational skills
- Analytical mindset
PythonJavaJob Description:
Test Design & Execution
Design and execute detailed, well-structured test plans, test cases, and test scenarios to ensure high-quality product releases.
Automation Development
Develop and maintain automated test scripts for functional and regression testing using tools such as Selenium, Cypress, or Playwright.
Defect Management
Identify, log, and track defects through to resolution using tools like Jira, ensuring minimal impact on production releases.
API & Backend Testing
Conduct API testing using Postman, perform backend validation, and execute database testing using SQL/Oracle.
Collaboration
Work closely with developers, product managers, and UX designers in an Agile/Scrum environment to embed quality across the SDLC.
CI/CD Integration
Integrate automated test suites into CI/CD pipelines using platforms such as Jenkins or Azure DevOps.
Required Skills & Experience
- Minimum internship experience in Software Quality Assurance or Automation Testing.
- Hands-on experience with Selenium WebDriver, Cypress, or Playwright.
- Proficiency in at least one programming/scripting language: Java, Python, or JavaScript.
- Strong experience in functional, regression, integration, and UI testing.
- Solid understanding of SQL for data validation and backend testing.
- Familiarity with Git for version control, Jira for defect tracking, and Postman for API testing.
Desirable Skills
- Experience in mobile application testing (Android/iOS).
- Exposure to performance testing tools such as JMeter.
- Experience working with cloud platforms like AWS or Azure.
We're building the AI operating system for the $600B global managed IT market.
Managed service providers (MSPs) run IT for lots of small and mid-sized businesses. Their technicians spend most of the day on repetitive tickets — setting up new joiners, sharing folders, fixing sign-in issues. Our first product is an AI service desk. It learns how each MSP works, turns a ticket into a plan of exact steps, and runs only what a technician approves.
Our vision is to build additional products for other parts of the MSP's business (such as voice AI, business operations and analytics), turning this into the one AI operating layer for the MSP business.
We've just raised a $4.4M pre-seed from Seedcamp, Futurepresent and Entree Capital. Our founders previously built upGrad ($2B) and Kapiva ($250M), and come from Bain Capital, Parthenon, and Morgan Stanley. Our co-founders both studied CS at IIT Delhi.
We're building a small team with very high talent density in Mumbai — people from IIT Bombay, Yale, Rippling and more.
The role:
We're hiring our first Product Designer — someone who will shape how the product looks, feels, and works from the ground up.
The hardest design problem we have is trust. A technician needs to feel comfortable letting AI make changes in a customer's Microsoft 365 or Google Workspace. So every screen needs to make it very clear what the AI knows, what it plans to do, and what it changed — and still be fast enough that a busy service desk actually uses it.
You'll work directly with the co-founder who leads product and our engineers, and own design end to end — from customer calls to shipped product.
What you'll do:
- Own the product experience end to end. Take problems from a first customer conversation to rough sketches, prototypes, and polished UI that ships — then keep improving it once it's live.
- Design how people and AI work together. Decide how the product explains what it knows, asks for approval, shows its progress, and owns up when something goes wrong. Make it easy for a technician to say yes with confidence.
- Make complex work feel simple. IT work is detailed and technical. You'll turn it into clear, fast experiences that busy teams can use without training.
- Stay close to customers. Join customer calls, watch technicians at work, test ideas with them every week, and bring what you learn straight into the product.
- Prototype fast, ideally in code. Use AI and design tools (Claude, Figma and others) to build working prototypes, so we learn from real use rather than static mockups.
- Design everywhere the product shows up — the app, integrations with tools technicians already use, operational dashboards and more.
- Build a lean design system. Give our engineers the building blocks to ship consistent UI without waiting on you.
- Set the bar for design. As our first designer, you'll shape how design is done here — the standard of quality, how we work, and who we hire next.
A few problems you might pick up in your first months: a single approval to set up 50 new joiners, with a clear "48 done, 2 need attention — and why"; a way for teams to see what the AI has learnt about each client, where it came from, and how to undo it; and a simple view that tells an owner the AI is working.
What we're looking for:
- Great product design work you've actually shipped. Consumer or B2B doesn't matter — we care much more about how you think than where you've worked.
- Strong craft and taste. Simple, clean and fast over flashy — think Linear, not a design studio website.
- Comfort going deep on a complex subject. You'll need to learn how things like Microsoft 365 groups and licences work, and enjoy doing it.
- Speed. You prototype in code or with AI tools and get ideas in front of users quickly.
- You use AI every day. You have opinions on what makes AI products feel trustworthy — and what makes them feel risky.
- High ownership and clear writing. You can take a messy problem all the way to something shipped, and explain your thinking simply along the way.
Nice to have:
- You've designed AI or agent products before.
- Early-stage startup or founder experience.
- You can write front-end code (React / Tailwind).
Probably not the right fit if
- Most of your work is brand, marketing, or research.
- You need a detailed spec and a design manager to do your best work.
Why join us?
- Real ownership. We're very early, so you'll shape how design works here — not inherit someone else's system.
- A hard, new problem. AI that takes real actions on real systems is still being figured out. You'll help define what good looks like.
- Fast impact. You'll work directly with the founders and see your work in customers' hands within weeks.
PythonSnowflake Administrator
What You’ll Do
- Observability: Monitor Snowflake queries, virtual warehouses, tasks, data loads, and overall account health. Identify and resolve operational issues.
- FinOps & Cost Optimization: Monitor credit consumption, storage, and warehouse costs. Optimize warehouse sizing, auto-suspend settings, and resource monitors.
- User Management: Manage Snowflake users, roles, onboarding, offboarding, and Role-Based Access Control (RBAC).
- Privilege Access Management: Review grants, privileged roles, access policies, and audit logs to enforce the principle of least privilege.
- Platform Maintenance: Maintain Snowflake account settings, integrations, and routine operational health checks.
- Service Desk Management: Triage incidents and service requests, investigating query failures, access issues, and platform-related problems.
- Enhancements & Automation: Improve Snowflake configurations, automate operational tasks, and streamline support processes.
- Business Continuity & Recovery: Support backup and retention policies, Time Travel, Fail-safe, and data recovery procedures.
- Deployment & CI/CD: Support controlled releases of Snowflake objects, roles, scripts, and configurations through CI/CD pipelines.
- Data Load Troubleshooting: Resolve issues related to Snowpipe, COPY commands, stages, file formats, connectivity, and scheduled data loads.
- Transformation & Data Model Support: Perform first-line troubleshooting of failed tasks, SQL errors, and schema changes.
- Functional Data Support: Investigate initial data availability and quality issues, coordinating with data owners for resolution.
- Project Support: Assist engineering teams with Snowflake environments, integrations, and migrations.
- Documentation: Maintain runbooks, access management procedures, operational guides, and knowledge base articles.
What We’re Looking For
- 5+ years of experience in data platform administration, operations, or production support, including hands-on Snowflake experience.
- Strong knowledge of Snowflake administration, including RBAC, virtual warehouses, query history, performance tuning, and cost optimization.
- Hands-on experience with Snowflake data loading, stages, tasks, Snowpipe, and cloud platforms such as AWS or Azure.
- Proficiency in SQL and familiarity with Python for scripting and automation.
- Experience with CI/CD pipelines, Jira, ITSM processes, and monitoring or automation tools.
- Strong troubleshooting, documentation, communication, and stakeholder management skills.
React.jsPythonWe are looking for a Senior Full Stack Engineer to join our lean, high-impact engineering team. This is a key founding-team role where you will work closely with the CTO and help build the engineering foundation of the company.
The ideal candidate is a backend-strong full-stack engineer with solid Python and React experience, a strong understanding of AI/LLMs, and the ability to independently take ownership of projects from idea to production.
What You'll Do:
- Build and scale applications across the backend and frontend
- Develop backend services and APIs using Python
- Build and maintain frontend applications using React
- Design and implement AI/LLM-powered applications and features
- Work with AI services and integrate them into real-world applications
- Contribute to system design and architecture
- Work with cloud infrastructure and services
- Take ownership of features and initiatives from ideation to production
- Identify problems and proactively drive solutions without requiring constant direction
- Work closely with the CTO and founding team to shape engineering practices and future systems
- Communicate technical concepts clearly to technical and non-technical stakeholders
What We're Looking For:
- 3–6 years of software engineering experience
- Strong experience with Python
- Good hands-on experience with React
- Strong backend development experience with full-stack exposure
- Practical understanding of AI, LLMs and AI services
- Experience building at least one meaningful AI project beyond basic API/chatbot integrations
- Experience taking an AI/ML application or feature into production is preferred
- Exposure to cloud platforms
- Good understanding of system design and software architecture
- Strong problem-solving and ownership mindset
- Excellent communication skills and ability to explain complex technical concepts in simple language
- Genuine hands-on experience with the technologies mentioned on the resume
What Makes This Role Different:
This is not a typical execution-focused engineering role. We are building a lean "A-team" of experienced engineers who will eventually help shape the team and take on senior/leadership responsibilities.
We're looking for someone who:
- Takes initiative rather than waiting for tasks
- Can work independently in an early-stage environment
- Is comfortable exploring and building with AI
- Can go deep into the work they've done and explain the technical decisions behind it
- Wants significant ownership and influence over the product and engineering direction
Location & Compensation
- Work Mode: Remote initially
- Future Location: Expected relocation to Bangalore in approximately 1 year
- Working Hours: Regular IST hours
- Travel: Potential opportunities to travel to Germany
Interview Process:
3 Rounds
- Technical & Project Deep Dive – Conversational discussion around past projects, AI experience and technical depth
- System Design & Technical Round – Deeper technical and architecture discussion
- Founder Round – Communication, culture fit, ownership and initiative
Amazon Web Services (AWS) Kubernetes
About the company:
We empower US healthcare payers with a truly next-generation, cloud-native, holistic, and customizable platform designed to prevent and adapt to the ever-evolving inaccuracies in healthcare claims and payments. By reducing complexity and administrative costs, we offer a unified, healthcare-dedicated platform backed by top VCs like BeeNext, 3One4 Capital, and Saison Capital.
Position Overview:
We are looking for an experienced DevOps Engineer to join our team in Bengaluru. In this role, you will be responsible for building, optimizing, and maintaining scalable, secure, and highly available multi-cloud infrastructure that supports our engineering teams. The ideal candidate brings strong hands-on experience with Kubernetes, Infrastructure as Code (Terraform), and robust monitoring/observability stacks to enable seamless, reliable, and automated deployments.
Key Responsibilities:
- Container Orchestration: Deploy, scale, and manage containerized workloads on Kubernetes (EKS, AKS, and GKE).
- Infrastructure as Code (IaC): Build and maintain modular, reusable, and version-controlled infrastructure using Terraform across AWS, Azure, and GCP.
- Monitoring & Observability: Set up, manage, and optimize monitoring, logging, and alerting stacks (e.g., Prometheus, Grafana, ELK/EFK, Loki, Datadog).
- CI/CD Pipeline Management: Own, improve, and automate CI/CD pipelines to enable fast, reliable, and frictionless software releases.
- System Reliability & SRE Practices: Implement best practices for system reliability, including defining SLIs/SLOs, managing incident response, and participating in on-call support.
- Troubleshooting & Support: Diagnose and resolve complex production issues across infrastructure, networking, and application layers.
- Security & Compliance: Implement infrastructure security best practices, including IAM policies, secrets management, and network security.
- Automation: Eliminate repetitive operational tasks by writing clean, efficient scripts in Python, Bash, or Go.
- Operations & Planning: Participate in capacity planning, cost optimization, disaster recovery, and infrastructure scaling initiatives while maintaining clear documentation and runbooks.
Requirements :
- Solid working experience with cloud providers, specifically AWS, Azure, or GCP.
- Strong understanding of containerization (Docker) and container orchestration concepts.
- Familiarity with Linux system administration and networking fundamentals.
- Experience with version control systems (Git) and GitOps workflows (ArgoCD/Flux is a plus).
- Strong problem-solving skills and the ability to thrive in a fast-paced, collaborative environment.
Qualifications :
Bachelor’s or Master’s degree in Computer Science, Information Technology, or a related technical field (or equivalent practical experience)
Key Skills:
- The ideal candidate must possess deep expertise in container orchestration, specifically hands-on experience managing Kubernetes ecosystems—including Helm charts, cluster networking, and RBAC policies—alongside a foundational mastery of Docker containerization.
- Proficiency in managing cloud architecture as software is essential, with a heavy emphasis on Terraform execution, including advanced module creation, state management, and multi-environment workspaces.
- A strong capability to implement full-stack visibility is required, utilizing tools like Prometheus, the Grafana LGMT stack, ELK/EFK, or Loki to build highly optimized monitoring, alerting, and logging systems.
- Candidates should have a proven track record of constructing and scaling automated deployment pipelines using industry-standard platforms such as Jenkins, GitLab CI, GitHub Actions, or Azure DevOps to minimize release friction. .
- Strong core programming fundamentals are required to automate repetitive infrastructure tasks, with practical proficiency in Python, Bash, or Go.
- Familiarity with cutting-edge cloud-native technologies is highly desirable, including enterprise service meshes (Istio, Linkerd), comprehensive cloud security frameworks (HashiCorp Vault, OPA, Trivy), and a data-driven approach to cloud cost management and FinOps practices.
Work Location: Jayanagar - Bangalore.
Work Mode: Work from Office, hybrid- 3 days WFO
Note: We are looking for immediate joiners & Bangalore Candidates only
Benefits:
- Best-in-class compensation
- Health insurance for Family
- Personal Accident Insurance
- Friendly and Flexible Leave Policy
- Certification and Course Reimbursement
- Medical Coding CEUs and Membership Renewals
- Health checkup
- And many more!
Python- Business: Immerse in operations until you think like an insider.Rapidly acquire domain expertise through direct observation, translate between business and engineering seamlessly, and mentor engineers in your area on immersion. Influence senior stakeholders effectively, manage complex stakeholder landscapes with competing agendas, and build trust rapidly with new stakeholders.
- Delivery: Lead rapid delivery initiatives across teams in your area, coach on prototype-first approaches, and establish trust through consistent fast delivery. Build complete applications rapidly across any technology stack, select the right tools for each problem, and define clear criteria for prototype-to-production transitions.
- Generative AI: Architect RAG systems for complex use cases across teams, implement advanced techniques (hybrid search, reranking, query expansion), mentor engineers on RAG best practices, and establish RAG standards. Lead evaluation strategy across teams, establishing annotation guidelines, training human-calibrated LLM judges, and building evaluation pipelines that connect tracing to datasets to experiments.
- People: Build high-performing teams across your area, navigate complex interpersonal dynamics, foster psychological safety, and create environments where diverse perspectives are valued. Influence through communication at all levels — from frontline to executive. Handle difficult conversations skilfully and train engineers in your area on effective communication.
- AI-Augmented Development: Optimise AI tool usage across teams in your area, train engineers on AI-augmented and agentic engineering workflows, evaluate new AI development tools, and establish practices that balance AI speed with verification rigour.
- Scale: Design complex multi-component systems end-to-end, evaluate architectural options for large initiatives across teams, guide technical decisions or your area, and mentor engineers on architecture. Create debt reduction strategies across teams, influence roadmap decisions to include debt work, and teach engineers when to accept debt for speed versus when to invest in quality.
What You Bring
- Bachelor’s degree in computer science, Software Engineering, or related field with 7+ years of relevant professional experience.
- Deep production experience with Python and JavaScript/TypeScript across backend and frontend, with demonstrated ability to work comfortably across the full stack.
- Strong experience with modern frontend frameworks (such as Next.js or React) and backend API development.
- Extensive experience with cloud platforms (AWS preferred; Azure or GCP also valued), including infrastructure-as-code tools (such as CloudFormation or Terraform).
- Deep Working knowledge of multiple database paradigms, including relational databases (such as PostgreSQL), document databases, and key-value stores (such as Redis), with the ability to select the right storage technology for each problem.
- Strong experience with CI/CD pipelines (such as GitHub Actions), containerisation, and production deployment strategies.
- Demonstrable fluency with AI coding tools (such as Claude Code, Cursor, GitHub Copilot, or similar) and proven ability to design agentic engineering workflows and train teams on AI-augmented development practices.
- Hands-on experience architecting production generative AI applications (LLM integrations, vector databases, RAG systems, evaluation pipelines) is essential.
- Experience leading technical initiatives across multiple teams, mentoring engineers, and establishing engineering practices is required.
- Experience navigating ambiguous problem spaces, working directly with business stakeholders and end users, and shipping working solutions rapidly is required.
- Experience in an embedded, forward-deployed, or consulting-style engineering model is a strong plus.
- Must have exceptional communication skills and demonstrated ability to influence at senior levels. This role requires comfort leading across ambiguous environments, building trust-based relationships with commercial stakeholders at all levels, developing junior and mid-level engineers, and making strategic decisions that balance delivery speed with architectural integrity. You will shape engineering practices across your area and be expected to lead multi-team initiatives.
PythonAbout the company
We are an AI diffusion company. We partner with midmarket companies in asset-heavy, regulated industries to co-build deeply industry-specific agentic and machine learning solutions, which then get diffused across the industry through revenue-share and equity-linked models.
Our Past
We have built and sold two companies, one of which was an AI company. Our founders and leaders are Math PhDs, Ivy League University Alumni, Ex-Googlers, and successful entrepreneurs.
Team
Our team of 20+ employees consists of data scientists, AI/ML Engineers, and mathematicians from top engineering and research institutes such as IITs, CERN, IISc, UZH. Our team includes academicians, IBM Research Fellows, and former founders. This role focuses on healthcare and RCM, working alongside our AI/ML engineers, data scientists and domain specialists.
Key Responsibilities
- Lead product ideation, solution design, and technical strategy from concept to execution.
- Drive end-to-end product development, translating business needs into scalable technical solutions.
- Build and lead engineering teams to deliver high-impact products.
- Design and develop robust data systems to process and structure unorganized data from ERP/CRM platforms.
- Leverage AI and domain expertise in healthcare/RCM to build innovative solutions.
- Drive technology-led growth, with a focus on product scalability and business outcomes.
\Required Skills & Experience
- 15–20 years of experience in technology leadership, preferably as a CTO or senior technology leader.
- Proven experience building and/ or exiting startups.
- Strong expertise in data engineering, complex data systems, and unstructured data processing.
- Experience with AI-driven products, preferably in healthcare or Revenue Cycle Management (RCM).
- Strong product thinking, system design, architecture, and end-to-end execution capabilities.
- Ability to translate business requirements into technical roadmaps and scalable products.




Similar companies

About the company
Jobs
5

About the company
Jobs
1

About the company
Jobs
0

About the company
Jobs
0
About the company
Jobs
0

About the company
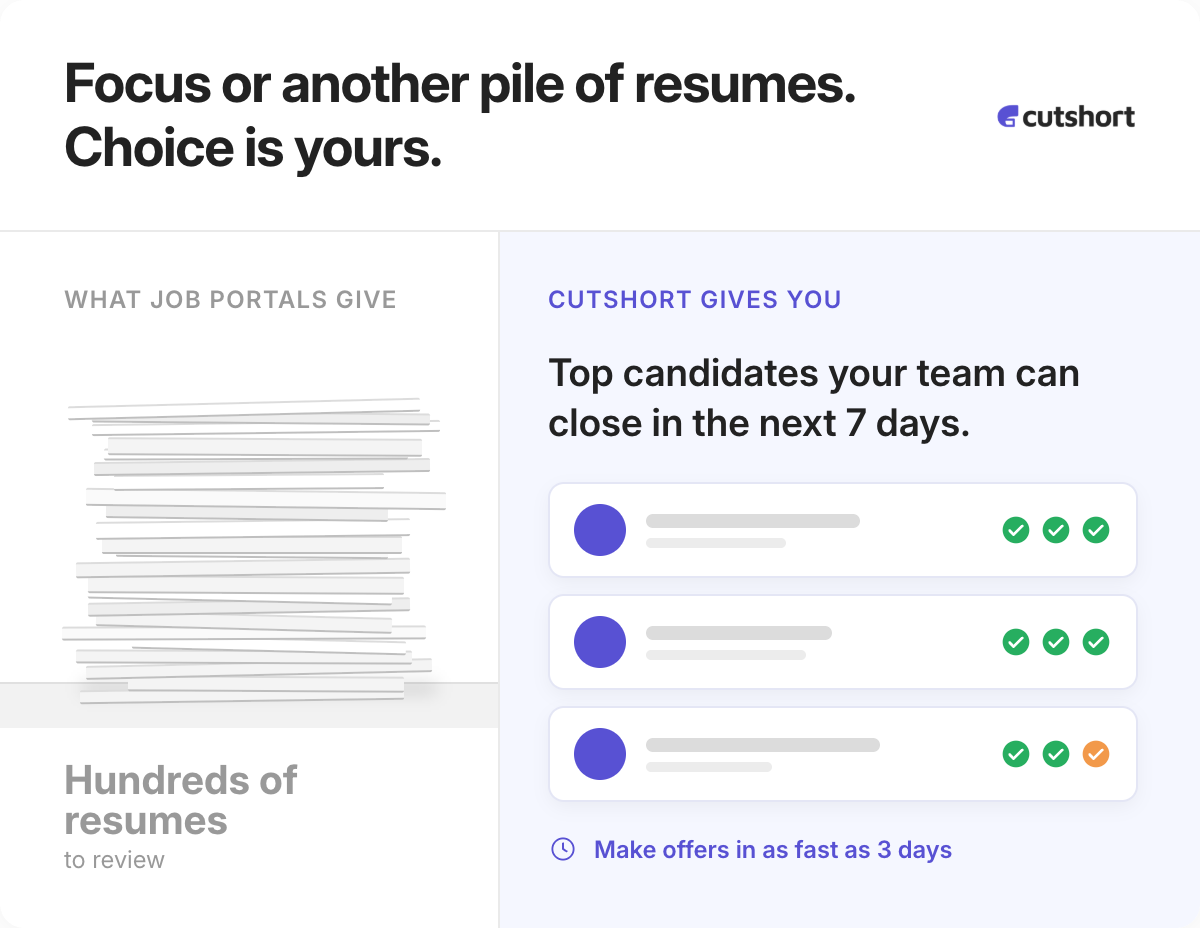
To hire better and faster, companies need rich candidate data, smart software and sound human judgement.
Cutshort is using AI to combine all these 3 to offer a 10x talent sourcing solution that is faster, better and cheaper.
We have 3 AI-powered offerings
- Hire using our AI platform: Affordable annual subscriptions
- Get only sourcing: 3.5% of annual CTC when you hire
- Get full recruiting: 6.99% of annual CTC when you hire
Customers such as Fractal, Sprinto, Shiprocket, Highlevel, ThoughtWorks, Deepintent have built strong engineering teams with Cutshort.
Jobs
1

About the company
Jobs
0

About the company
At Cutshort, we are building an unconventional startup to connect passionate professionals with each other. Using Artificial Intelligence (AI), gamification and network intelligence, our focus is to reduce noise and give high quality results to our users.
Our recruitment solution was launched first and is seeing good traction 2.20M+ users and ~20000 companies such as Google, Flipkart, Ola, Zomato, Oyo Rooms, HackerRank, BrowserStack have used the platform. So far, more than 8000 positions worth $17,500,000 have been closed by the hiring staff at these companies.
To experience the future, check out our latest product Voila: https://cutshort.io/voila
If you are smart and want to build something as big as LinkedIn, we might have a position for you. But before applying, be sure to read this blog post to see if you'd be a fit.
Jobs
16

About the company
Use the power of Artificial Intelligence to find jobs, hire people, meet other top professionals or otherwise succeed in your career.
Jobs
0
About the company
Test
Jobs
0
